Exploring Claude/GPT Knowledge Cutoffs and Pre-Training Timelines
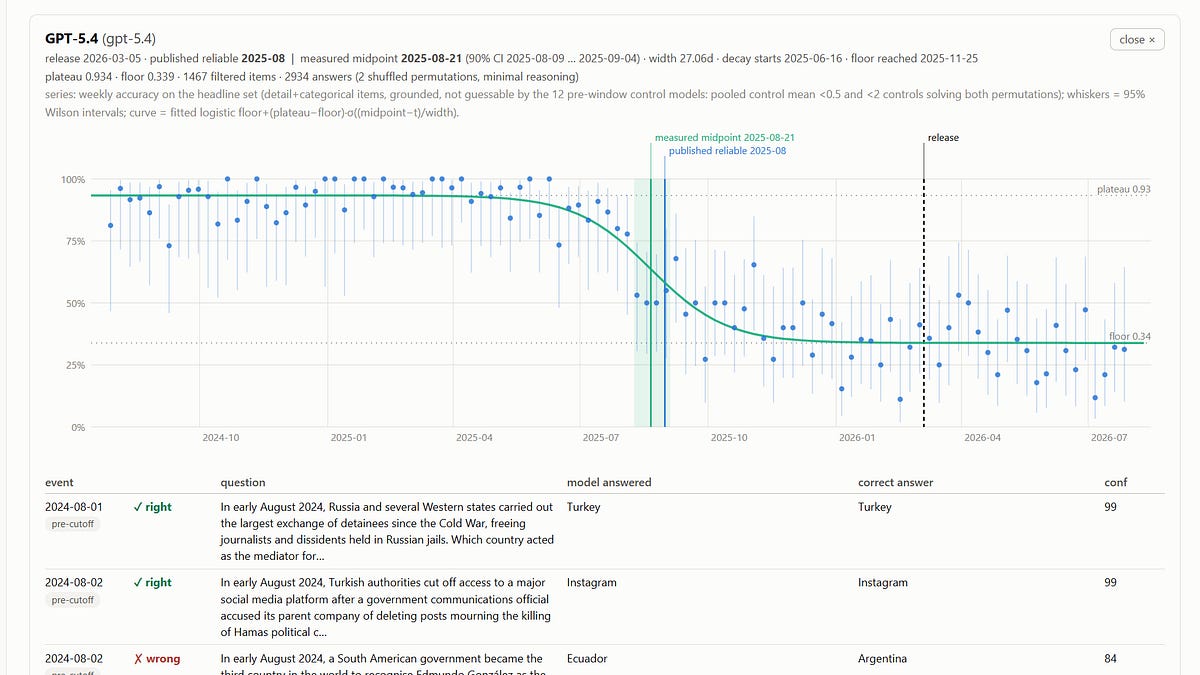
The post describes three probing techniques for extracting hidden training information from frontier LLMs: 'Incompressible Knowledge Probes' to estimate parameter counts, 'Data Mixture Inference' to reveal dataset composition via token breakdowns, and scoring models on date/self-identification questions to estimate training timelines. It explains the typical three-stage training pipeline: large-scale internet pre-training, domain-specific 'textbook quality' fine-tuning, and post-training to turn the base model into an assistant. Labs often release post-trained models from partially trained checkpoints, so public models may reflect the latest checkpoint plus the best post-training techniques.
To estimate pre-training checkpoint dates, the author built a dataset of daily Wikipedia facts (e.g., '2025 in the United States') and gave each model an 8-way multiple-choice quiz on events from specific days. By analyzing the error-rate timeline, they aim to pinpoint when the model's training data loses signal about a given date. The post notes that all estimates are speculative, as there is little public ground truth to verify against.